Load Test Report Template: Benchmarks and Bottlenecks
A standardized template for documenting load test results: throughput, latency percentiles, error rates, bottlenecks with evidence, and action items — with a worked k6 example.
Overview
A load test report is how performance findings reach stakeholders — and how you prove next quarter’s run actually got better. Skip the standard format and every report turns into a fresh explanation: what was tested, which metrics mattered, what the numbers mean. The findings that should have triggered work get lost in the noise. This template gives you a consistent structure: an executive summary for decision-makers, scannable tables for engineers, and action items with owners so results actually turn into fixes.
It’s the reporting half of a load test — the planning half lives in the Load Test Plan Template.
When to Use
- Reporting results after a scheduled load test cycle
- Sharing performance findings with product managers or executives
- Creating a baseline before a major release or infrastructure change
- Validating a fix after a performance incident
Solution
# Load Test Report

## 1. Executive Summary

| Field | Value |
|-------|-------|
| Application / Service | `name` |
| Test Date | `YYYY-MM-DD` |
| Environment | `staging / production-like` |
| Tool Used | `k6 / JMeter / Gatling / Locust` |
| Tester | `name` |
| Aggregate Result | `PASS / PASS with warnings / FAIL` |

- **Goal**: Briefly state what was tested and why.
- **Key Finding**: One-line summary of the most important result.

## 2. Test Scope

- **Endpoints tested**: List URLs or user flows
- **Load profile**: Concurrent users, ramp-up, duration, steady state
- **Data used**: Realistic datasets, anonymized production data, or synthetic

## 3. Results

### Throughput

| Metric | Target | Actual | Status |
|--------|--------|--------|--------|
| Requests/sec | 1,000 | 1,150 | PASS |
| Transactions/sec | 500 | 480 | PASS |

### Latency (ms)

| Percentile | Target | Actual | Status |
|------------|--------|--------|--------|
| p50 | < 100 | 85 | PASS |
| p95 | < 300 | 320 | WARNING |
| p99 | < 500 | 680 | FAIL |

### Error Rate

| Metric | Target | Actual | Status |
|--------|--------|--------|--------|
| HTTP 5xx | < 0.1% | 0.05% | PASS |
| Timeout | < 0.01% | 0.00% | PASS |

### Resource Utilization

| Resource | Target | Peak | Status |
|----------|--------|------|--------|
| CPU | < 70% | 65% | PASS |
| Memory | < 80% | 82% | WARNING |
| DB Connections | < 80% | 78% | PASS |

## 4. Bottlenecks Identified

1. **Bottleneck**: Database query X takes 400ms under load
   - **Impact**: p99 latency exceeds target
   - **Evidence**: Query plan screenshot, APM trace link
   - **Recommendation**: Add composite index on `(user_id, created_at)`

2. **Bottleneck**: Connection pool exhaustion at 1,200 users
   - **Impact**: 503 errors spike
   - **Evidence**: Pool metrics dashboard link
   - **Recommendation**: Increase pool size from 20 to 40

## 5. Action Items

| Priority | Action | Owner | Due Date |
|----------|--------|-------|----------|
| P0 | Add DB index on query X | @backend-team | 2026-06-28 |
| P1 | Increase connection pool | @devops-team | 2026-06-25 |
| P2 | Evaluate caching layer | @architect | 2026-07-05 |

## 6. Appendices

- Link to test script repository
- Link to raw results / CSV exports
- Link to APM dashboards (Grafana, Datadog)
- Link to incident runbook if follow-up is needed
Explanation
The template separates summary (for executives), details (for engineers), and actions (for planning). The tabular Target/Actual/Status format makes pass/fail scannable at a glance — nobody should have to read three paragraphs to learn p99 blew the budget. Each bottleneck links to evidence, so a reviewer can check the claim instead of taking your word for it. And action items get owners and dates, which is the difference between a report that changes things and one that gets skimmed and archived.
Worked Example: Load Testing an E-commerce Checkout Flow
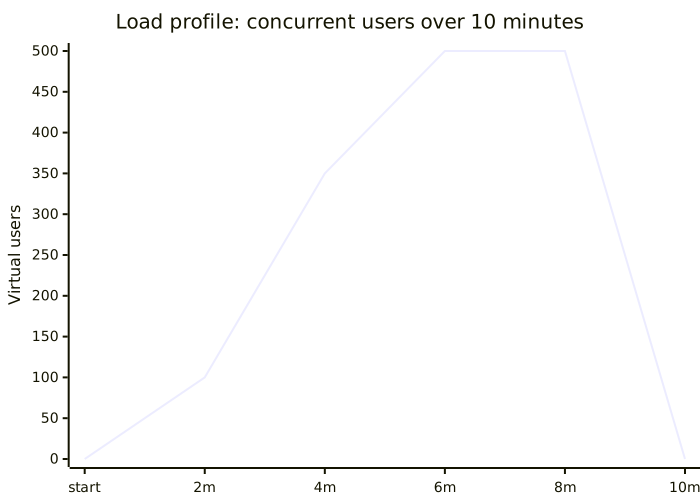
A 500-user checkout test run with k6 — the script, the raw results, and how they map onto the template:
// checkout_load.js — 500-user ramp with SLO thresholds
import http from "k6/http";
import { check, sleep } from "k6";

export const options = {
  stages: [
    { duration: "2m", target: 100 },  // ramp up
    { duration: "5m", target: 500 },  // climb to peak
    { duration: "2m", target: 500 },  // hold steady state
    { duration: "1m", target: 0 },    // ramp down
  ],
  thresholds: {
    http_req_duration: ["p(95)<300", "p(99)<500"],
    http_req_failed: ["rate<0.01"],
  },
};

export default function () {
  const res = http.post("https://staging.example.com/api/checkout",
    JSON.stringify({ cart_id: "cart_123", payment_method: "card" }),
    { headers: { "Content-Type": "application/json" } });
  check(res, {
    "status is 201": (r) => r.status === 201,
    "response has order_id": (r) => r.json("order_id") !== undefined,
  });
  sleep(1);
}
Run it with k6 run --out json=results.json checkout_load.js. Hypothetical outcome:
- p50 latency: 85ms (target < 100ms) PASS
- p95 latency: 320ms (target < 300ms) WARNING
- p99 latency: 680ms (target < 500ms) FAIL
- Error rate: 0.05% (target < 0.1%) PASS
- Throughput: 1,150 req/s (target 1,000) PASS
The bottleneck analysis that belongs in section 4: the order_items query takes 400ms under load (missing composite index on (order_id, product_sku)), and the connection pool exhausts at 1,200 concurrent users. Result: P0 index, P1 pool increase 20→40, P2 Redis cache for product lookups — each with an owner and a date.
Variants
| Context | Approach | Notes |
|---|---|---|
| Pre-release | Baseline comparison | Include previous release numbers side-by-side |
| Incident recovery | Post-fix validation | Focus on the specific path that failed |
| Capacity planning | Saturation test | Document the breaking point and limiting resource |
| Regression gate in CI | Threshold summary only | Report just the failed thresholds and trends |
What Works
- Run tests in an environment that mirrors production — hardware, data size, and network all matter more than people expect.
- Always warm up first; cold-start numbers poison a report before it begins.
- Report percentiles (p50, p95, p99) instead of averages so tail latency doesn’t hide.
- Static numbers age badly — link live dashboards and include the graphs.
- Attach the exact test script so anyone can reproduce the run.
Common Mistakes
- Testing on developer laptops or undersized environments.
- Testing against a 50-row dataset and wondering why prod is slower.
- Reporting only average latency, which hides p99 degradation.
- Omitting error rates and focusing only on throughput.
- Leaving required fields blank or writing vague one-word answers.
- Filling the report once and never updating it after follow-up work changes the picture.
- Not assigning an owner and due date to action items, so nothing gets fixed.
Troubleshooting
- Results look suspiciously good. Usually warm-up wasn’t excluded, or test data kept hitting cache. Check cache hit rates and dataset size before celebrating.
- The test crashes before the system does. The load generator is the bottleneck — one machine can’t push enough. Split across runners (k6 Cloud, distributed JMeter) or reduce think time.
- Latencies too low to be true. The test ran on the same machine or network segment as the server — numbers measured on localhost say nothing about real user experience.
- Thresholds pass but users still complain. You’re measuring the wrong percentile or the wrong endpoints — p50 can look great while a heavy checkout endpoint degrades at p99.
- Numbers differ wildly between runs. The environment isn’t isolated — someone else’s job, a noisy neighbor VM, or an autoscaling event contaminated the run. Note the conditions in the report’s Environment field.
Further Reading
Frequently Asked Questions
How do I define targets for latency and throughput?
Targets should come from SLAs, product requirements, or historical baselines — never from what the tool happens to produce. If none exist yet, use the 80th percentile of current production traffic as a starting point — see Monitoring & Alerting Policy Template for how SLO-driven targets get formalized.
Should I run load tests against production?
Resist the temptation. A load test against production can take down the very thing you're trying to protect — I've seen a "quick check" saturate a connection pool during business hours. Test somewhere that looks like production instead: same data volume, same infrastructure class, no live users to hurt. For read-only endpoints, traffic mirroring or shadow testing gets you real-world shape without the risk.
How often should load tests be repeated?
Before every major release and after infrastructure changes, plus a quarterly regression check. A small nightly smoke test with modest load catches most regressions before they ever reach a report.
What percentiles should I report?
Start with p50, p95, and p99 — the typical experience, the bad day, and the tail. p95 catches most degradation while p99 surfaces the latency spikes that hit real users. If you've got SLOs at p99.9, include that too. Never report only averages — they hide tail latency spikes.
How do I simulate realistic user behavior in load tests?
Use think time (pauses between actions) to match real user patterns. Distribute requests across endpoints proportionally to production traffic — browsing, searching, and checkout flows, not just the heaviest endpoint. Parameterize test data so each virtual user hits different records; otherwise cache hits skew the results.
Related Resources
Load Testing APIs with k6 and Threshold-Based Assertions
How to write and run load tests with k6 to measure API performance, validate SLOs, and identify bottlenecks before production deployment
DocLoad Test Plan Template
Fillable load test plan template: scenarios, ramp-up profiles, pass/fail thresholds, monitoring setup, and ready-to-run k6, JMeter and Locust scripts.
DocTest Coverage Report Template
A template for reporting test coverage by module, feature, and critical path with trend analysis and gap identification.
DocAPI Testing Strategy Template
A template for planning contract tests, integration tests, and load tests for APIs.
DocMonitoring and Alerting Policy Template
A policy template that defines how alerts are configured, routed, escalated, and reviewed across services and infrastructure.
GuideSoftware Testing Strategy Guide
A practical guide to building a layered testing strategy with unit, integration, contract, and end-to-end tests that your team will actually maintain.