Complete Guide to Microservices Communication
Compare sync vs async communication patterns for microservices. Covers REST, gRPC, message queues, event-driven, service mesh, and when to use each.
Introduction
Splitting a monolith into services moves your function calls onto the network. That single change — from in-process invocation to remote call — is where most microservices projects win or lose. Calls that used to take microseconds now take milliseconds, can time out, can be retried, and can silently duplicate work on the other side.
The communication pattern you pick for each hop decides how latency adds up, what happens when a dependency is down, how tightly services are coupled, and how painful the system is to operate at 3 a.m. This guide compares the synchronous patterns (REST, gRPC), the asynchronous ones (message queues, pub/sub, the outbox pattern), and the infrastructure layer (API gateway, service mesh), with working code and decision criteria for each. It assumes you already run two or more services and need to wire them together — if you’re still deciding whether microservices are right for your system, start with the microservices architecture guide first. All the code in this guide is also available as standalone files in the companion repository.
Synchronous vs Asynchronous
A synchronous call is a remote function call: the caller sends a request, blocks, and waits for a response. An asynchronous interaction hands a message to a broker and moves on — the work happens later, possibly in a service the caller doesn’t even know exists.
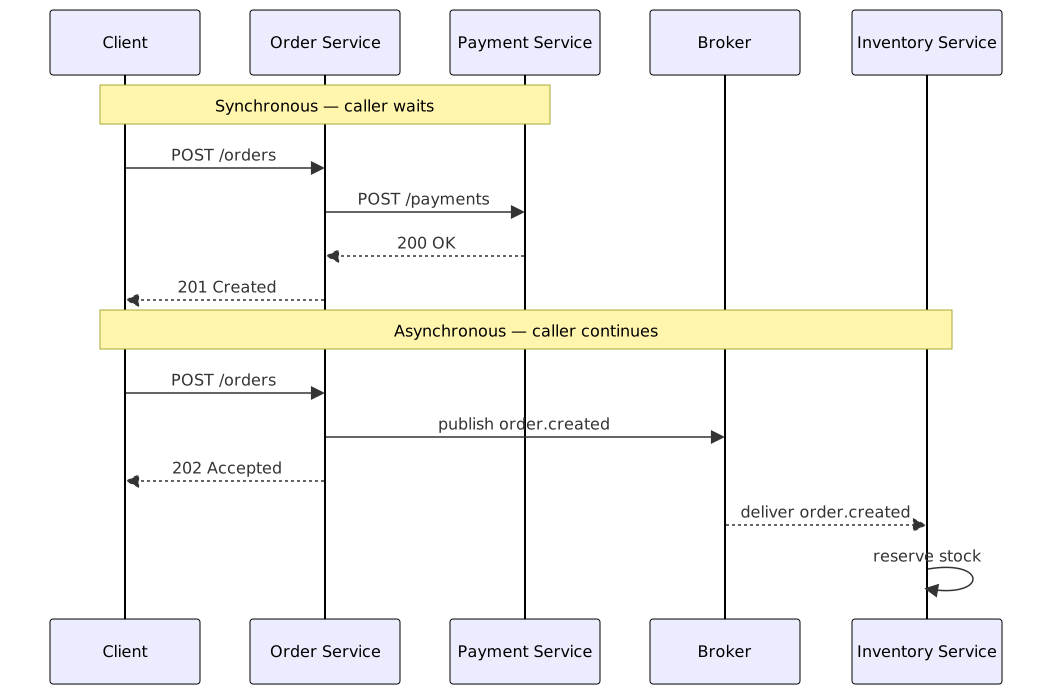
| Aspect | Synchronous | Asynchronous |
|---|---|---|
| Coupling | Tight (caller knows callee) | Loose (caller does not know callee) |
| Latency | Caller waits for response | Caller continues immediately |
| Failure | Caller fails if callee is down | Message persists, callee processes later |
| Scalability | Limited by slowest service | Better — services scale independently |
| Complexity | Simpler to implement | Requires broker, idempotency, ordering |
| Use Case | Read-heavy, low-latency | Write-heavy, decoupled workflows |
The table hides two costs that bite in production. On the sync side, latency compounds: if a request fans out to three services in series and each adds ~80 ms, the caller waits 240 ms plus network overhead before doing its own work. Availability compounds too — chain five calls at 99.9% uptime each and the chain lands you at roughly 99.5%. On the async side, you trade those costs for new ones: at-least-once delivery means duplicate processing unless consumers are idempotent, ordering is only guaranteed per partition, and “did it work?” becomes a question you answer with correlation IDs and monitoring instead of a status code.
Neither style is a default. Sync is the right call for reads and request/response flows where the client genuinely needs the answer now — a price lookup, an auth check. Async earns its complexity when work can be deferred, when several services react to the same event, or when you can’t afford a downstream outage to become your outage.
The Distributed Monolith Trap
The most common communication failure isn’t picking the wrong protocol — it’s rebuilding the monolith’s call graph over HTTP. You end up with services that can’t be deployed, scaled, or even restarted independently because every request threads through five of them.
The smell is easy to spot: a single user action triggers a chain like Order → Inventory → Pricing → Promotion → Shipping, each call synchronous, each one a new point of failure and a new hop of latency. The services look independent in the repo graph but behave as one fragile process. Roll out a change to Pricing and you end up redeploying Order anyway, because Order’s contract tests depend on it.
The fix isn’t “make everything async.” It’s removing hops that don’t need to exist:
- Cache or replicate read data. If Order needs the product name for its API responses, it shouldn’t call Catalog on every read — denormalize the field or subscribe to a
catalog.updatedevent and keep a local copy. - Move work off the request path. Sending a confirmation email or reserving inventory doesn’t need to finish before the client gets its 201. Publish an event and let the workers race ahead.
- Collapse fine-grained services. Two services that always change together and always call each other might be one service that was split too early.
Every synchronous hop you remove improves latency, availability, and deployability at the same time. When a hop must stay synchronous, protect it with timeouts, retries, and a circuit breaker — covered in the resilience section below.
Synchronous Patterns
REST (HTTP/JSON)
from fastapi import FastAPI, HTTPException
import httpx

app = FastAPI()

ORDER_SERVICE = "http://order-service:8000"
PAYMENT_SERVICE = "http://payment-service:8000"

@app.get("/orders/{order_id}/summary")
async def order_summary(order_id: str):
    async with httpx.AsyncClient(timeout=5.0) as client:
        try:
            order = await client.get(f"{ORDER_SERVICE}/orders/{order_id}")
            order.raise_for_status()
            payment = await client.get(f"{PAYMENT_SERVICE}/payments/{order_id}")
            payment.raise_for_status()
        except httpx.HTTPError as e:
            raise HTTPException(status_code=502, detail=f"Upstream error: {e}")

    return {
        "order": order.json(),
        "payment": payment.json(),
    }
REST remains the default because it debugs itself: you can curl an endpoint, read the payload, and reproduce a bug from a ticket without tooling. The trade-offs are payload size (JSON is verbose), head-of-line blocking on HTTP/1.1, and no built-in contract — the consumer finds out about a breaking change when production calls start failing.
Two details in this example matter more than they look. The timeout=5.0 isn’t optional decoration — without it a hung payment service holds your connection (and your thread or coroutine) forever. And both fetches happen inside one client, so the two calls can run concurrently if you refactor them with asyncio.gather; the sequential version shown here is the simple case, not the fast one.
When to use REST:
- Public APIs, external integrations
- CRUD operations
- Human-readable payloads
- Browser-facing endpoints
When to avoid it: high-frequency internal calls where serialization dominates CPU, or anything that needs streaming — that’s gRPC territory.
gRPC (HTTP/2 + Protobuf)
syntax = "proto3";

service OrderService {
  rpc GetOrder (OrderRequest) returns (OrderResponse);
  rpc CreateOrder (CreateOrderRequest) returns (OrderResponse);
}

message OrderRequest {
  string order_id = 1;
}

message OrderResponse {
  string order_id = 1;
  string status = 2;
  double total = 3;
}
import grpc
import order_pb2
import order_pb2_grpc
def get_order(order_id: str) -> order_pb2.OrderResponse:
with grpc.insecure_channel("order-service:50051") as channel:
stub = order_pb2_grpc.OrderServiceStub(channel)
return stub.GetOrder(order_pb2.OrderRequest(order_id=order_id))gRPC trades REST’s readability for speed and guarantees. Protobuf payloads are compact binary, HTTP/2 multiplexes calls over one connection, and the .proto file is a versioned contract — field numbers make schema evolution explicit instead of “hoping nobody renames a JSON key.” Streaming (server, client, or bidirectional) is a first-class feature, which REST can’t express at all.
The costs: browsers can’t speak gRPC natively (you’d need gRPC-Web or a gateway), payloads aren’t human-readable without a decoder, and the stub generation step adds friction for polyglot teams. Deadlines are your equivalent of timeouts — set them on every call, because gRPC propagates cancellation through the chain and a missing deadline at the top means wasted work all the way down.
When to use gRPC:
- Internal service-to-service communication
- High-throughput, low-latency requirements
- Strong typing across languages
- Streaming (bi-directional, server-streaming)
For a deeper guide, see gRPC in Microservices — High-Performance RPC Guide.
Asynchronous Patterns
Message Queue (Point-to-Point)
import pika
import json

connection = pika.BlockingConnection(pika.ConnectionParameters("rabbitmq"))
channel = connection.channel()
channel.queue_declare(queue="order_created", durable=True)

# Producer — Order service publishes a message
def publish_order_created(order_id: str, customer_id: str):
    message = json.dumps({"order_id": order_id, "customer_id": customer_id})
    channel.basic_publish(
        exchange="",
        routing_key="order_created",
        body=message,
        properties=pika.BasicProperties(delivery_mode=2),  # persistent
    )

# Consumer — Shipping service processes the message
def consume_orders():
    def callback(ch, method, properties, body):
        order = json.loads(body)
        print(f"Shipping order {order['order_id']}")
        ch.basic_ack(delivery_tag=method.delivery_tag)

    channel.basic_consume(queue="order_created", on_message_callback=callback)
    channel.start_consuming()
A queue is work distribution: each message lands with exactly one consumer, even when several are competing for it. That’s the right shape for “this task must happen once” — charge a card, generate a PDF, resize an image.
The details that keep you out of trouble live in the flags. durable=True on the queue plus delivery_mode=2 on the message means RabbitMQ writes the message to disk, so it survives a broker restart. basic_ack after processing — not on receive — means a consumer that crashes mid-task gets the message redelivered instead of losing it. The flip side: redelivery means your callback will run twice on poisoned messages and flaky handlers, so the consumer’s work must be safe to repeat.
When to use a queue: task offload, load leveling against spiky traffic, and integrations where the producer shouldn’t wait. When several services need the same fact — not the same task — you want pub/sub instead.
Event-Driven (Pub/Sub)
const { Kafka } = require("kafkajs");

const kafka = new Kafka({
    clientId: "order-service",
    brokers: ["kafka:9092"],
});

const producer = kafka.producer();
const consumer = kafka.consumer({ groupId: "inventory-group" });

// Producer — publish domain events
async function publishOrderCreated(order) {
    await producer.connect();
    await producer.send({
        topic: "order.created",
        messages: [
            {
                key: order.id,
                value: JSON.stringify({
                    orderId: order.id,
                    customerId: order.customerId,
                    items: order.items,
                    timestamp: Date.now(),
                }),
            },
        ],
    });
    await producer.disconnect();
}

// Consumer — multiple services subscribe to the same event
async function consumeOrderEvents() {
    await consumer.connect();
    await consumer.subscribe({ topic: "order.created", fromBeginning: false });

    await consumer.run({
        eachMessage: async ({ topic, partition, message }) => {
            const event = JSON.parse(message.value.toString());
            console.log(`Reserving inventory for order ${event.orderId}`);
            // Update inventory, then publish inventory.reserved event
        },
    });
}

consumeOrderEvents();
Pub/sub inverts the dependency: the producer announces a fact (order.created) and doesn’t know or care who reacts to it. Inventory, shipping, and analytics each subscribe with their own consumer group and process the same event independently — you can add a new consumer without touching the producer, which is the whole point of event-driven design.
Two mechanisms in this snippet carry the semantics. The key: order.id routes all events for one order to the same partition, and ordering is only guaranteed inside a partition — pick a key that groups the entities whose order matters. The groupId defines the competing-consumers boundary: two instances in inventory-group split partitions between them, while a second group gets its own independent copy of the stream.
The price you pay is eventual consistency — the next section covers what that means in practice. For the full pattern catalog, see the event-driven architecture guide.
Event-Driven with Outbox Pattern (Java)
import org.springframework.stereotype.Service;
import org.springframework.transaction.annotation.Transactional;
import org.springframework.jdbc.core.JdbcTemplate;

@Service
public class OrderService {

    private final JdbcTemplate jdbc;

    public OrderService(JdbcTemplate jdbc) {
        this.jdbc = jdbc;
    }

    @Transactional
    public void createOrder(Order order) {
        // 1. Save order
        jdbc.update(
            "INSERT INTO orders (id, customer_id, total) VALUES (?, ?, ?)",
            order.getId(), order.getCustomerId(), order.getTotal()
        );

        // 2. Save outbox event in the same transaction
        jdbc.update(
            "INSERT INTO outbox (aggregate_id, event_type, payload) VALUES (?, ?, ?)",
            order.getId(), "OrderCreated", order.toJson()
        );
    }
}

// Separate process reads outbox and publishes to Kafka
@Service
public class OutboxPublisher {

    private final JdbcTemplate jdbc;
    private final KafkaTemplate<String, String> kafka;

    public OutboxPublisher(JdbcTemplate jdbc, KafkaTemplate<String, String> kafka) {
        this.jdbc = jdbc;
        this.kafka = kafka;
    }

    @Scheduled(fixedDelay = 1000)
    public void publishPendingEvents() {
        var events = jdbc.queryForList(
            "SELECT id, aggregate_id, event_type, payload FROM outbox WHERE published = false LIMIT 100"
        );

        for (var event : events) {
            kafka.send("order." + event.get("event_type"),
                       (String) event.get("aggregate_id"),
                       (String) event.get("payload"));
            jdbc.update("UPDATE outbox SET published = true WHERE id = ?", event.get("id"));
        }
    }
}
The problem this solves is the dual-write: “INSERT order, then publish event” is two writes to two systems, and any crash between them leaves the database committed but the event lost — or worse, the event sent but the transaction rolled back. The transactional outbox pattern fixes it by making the event part of the same database transaction as the business write. A relay — the scheduled publisher here, or a CDC tool like Debezium in production — reads the outbox table and forwards to the broker.
One honest limitation: this publisher marks rows as sent after kafka.send, so a crash between send and update republishes the event. Consumers still need idempotency — the outbox gives you at-least-once, not exactly-once.
Consistency Models and Sagas
Synchronous calls give you strong consistency for free — the response is the truth at that moment. Events give you eventual consistency: after order.created is published, each consumer converges on the new state at its own pace, and for a window of time different services disagree about reality. That’s not a bug to fix; it’s the deal you signed. The mistake is pretending otherwise — for example, writing code that publishes an event and then immediately reads the downstream service expecting the result.
What do you do when a business process spans several services and must either complete or unwind? A saga: a sequence of local transactions where each step publishes the event that triggers the next, and each has a compensating action that undoes it if a later step fails.
| Style | How it works | Fit |
|---|---|---|
| Choreography | Services react to each other’s events — no central coordinator | Few steps (2–4), loosely coupled teams |
| Orchestration | A coordinator service tells each participant what to do next | Many steps, need visibility of process state |
Choreographed sagas emerge naturally from pub/sub — Order publishes order.created, Inventory reserves stock and publishes inventory.reserved, Payment charges and publishes payment.completed. The trap is that nobody owns the flow: when a refund fails three hops deep, reconstructing “where is this order?” means tailing events across services. Orchestration costs you a coordinator component, but the process state lives in one place and is queryable. Start with choreography; reach for orchestration (Temporal, Camunda, a simple state machine in your order service) when support starts asking “which step is this order stuck at?” and you can’t answer.
Resilience: Timeouts, Retries, and Idempotency
Every synchronous call needs all three, and most production incidents come from having only one.
- Timeouts bound the wait. Pick them from the callee’s real p99, not a guess — if payments answer in 300 ms p99, a 5 s timeout is generous, not tight.
- Retries absorb transient failures — a dropped TCP connection, a leader election. Retry with exponential backoff and jitter, and cap the attempts (2–3); beyond that you’re a retry storm multiplying load on an already-dying service.
- Idempotency makes retries safe. A
POST /paymentsretried after a timeout might have succeeded the first time — without an idempotency key, the customer gets charged twice.
import httpx
import uuid

def charge_payment(order_id: str, amount: int, idempotency_key: str | None = None):
    key = idempotency_key or str(uuid.uuid4())
    response = httpx.post(
        "http://payment-service:8000/payments",
        json={"order_id": order_id, "amount": amount},
        headers={"Idempotency-Key": key},
        timeout=httpx.Timeout(5.0, connect=2.0),
    )
    response.raise_for_status()
    return response.json()
The server stores the key with the result; a duplicate key returns the original response instead of re-executing. GET, PUT, and DELETE are idempotent by HTTP semantics — POST is not, and it’s usually POST that mutates money and stock.
Retries alone aren’t enough for a dependency that’s genuinely down, though — that’s what the circuit breaker pattern is for: after N consecutive failures it stops calling, fails fast, and probes recovery instead of queueing doomed requests behind timeouts. The async side has its own version of this contract: idempotent consumers keyed on event ID, dead-letter queues for poisoned messages, and consumer lag alerts so you notice before the queue is days deep.
Infrastructure Patterns
API Gateway
# Kong or NGINX API Gateway configuration
apiVersion: v1
kind: ConfigMap
metadata:
  name: gateway-routes
data:
  kong.yml: |
    routes:
      - name: order-service
        paths:
          - /orders
        service:
          name: order-service
          url: http://order-service:8000
      - name: payment-service
        paths:
          - /payments
        service:
          name: payment-service
          url: http://payment-service:8000
    plugins:
      - name: rate-limiting
        config:
          minute: 100
      - name: jwt
The gateway owns the north-south boundary: everything external traffic needs — routing, auth, rate limiting, request size limits, TLS termination — happens once, at the edge, instead of being reimplemented in every service. It also gives you one place to version APIs and deprecate routes.
Two warnings. First, keep business logic out of the gateway — the moment a route plugin encodes “if order total > 500 require approval,” you’ve built a bottleneck service nobody can test. Second, a gateway is a shared failure domain: when it falls over, everything falls over. Run it replicated and keep its config boring. See the API gateway design guide for the resilience patterns.
Service Mesh (Istio)
apiVersion: networking.istio.io/v1
kind: VirtualService
metadata:
  name: order-service
spec:
  hosts:
    - order-service
  http:
    - route:
        - destination:
            host: order-service
            subset: v1
            port:
              number: 8000
          weight: 90
        - destination:
            host: order-service
            subset: v2
            port:
              number: 8000
          weight: 10
---
apiVersion: networking.istio.io/v1
kind: DestinationRule
metadata:
  name: order-service
spec:
  host: order-service
  subsets:
    - name: v1
      labels:
        version: v1
    - name: v2
      labels:
        version: v2
  trafficPolicy:
    outlierDetection:
      consecutive5xxErrors: 5
      interval: 30s
      baseEjectionTime: 30s
A mesh handles east-west traffic — the service-to-service calls inside your cluster. A sidecar proxy next to each service takes over mTLS, retries, timeouts, circuit breaking, telemetry, and traffic splitting, so application code stops reimplementing them (usually inconsistently, in five languages). The config shown does a 90/10 canary split and ejects pods that return five consecutive 5xx responses — both are a few lines of YAML that would otherwise be a library integration per service.
The honest cost: meshes add an operational layer (control plane, proxy upgrades, a new debugging surface) and 1–5 ms per hop. They’re justified when you’ve got enough services that per-language resilience libraries became a maintenance problem — below that threshold, a shared HTTP client or a library like resilience4j covers most of it. Istio’s documentation is the reference for what’s actually configurable.
Service Discovery
Both patterns above assume callers can find callees — but in a container platform, order-service isn’t a machine, it’s a shifting set of pods. Options in rough order of complexity: Kubernetes DNS (order-service.default.svc resolves to healthy endpoints — free, no extra infrastructure), a broker-side load balancer (the mesh handles it), or a client-side registry like Consul or Eureka for non-Kubernetes estates. On Kubernetes you almost never need application-level discovery; reaching for Consul inside a cluster is usually paying for the same thing twice.
When Not to Use Each Pattern
Just as important as the “when to use” lists:
- Don’t go async for simple CRUD. If the client needs the saved record back to render a page, a queue buys you a
202 Acceptedplus a polling problem. - Don’t adopt gRPC for browser-facing or public APIs. REST plus JSON is the interoperable default; gRPC-Web works but adds a proxy layer to debug.
- Don’t deploy a service mesh at five services. The operational overhead outweighs per-language resilience libraries until the fleet is large enough that consistency is the actual pain.
- Don’t put an API gateway between internal services. East-west traffic goes through the mesh or direct calls; routing every internal hop through an edge component adds latency and a shared failure point.
- Don’t choreograph a twelve-step saga. Past a handful of steps, the flow logic lives in nobody’s code. Orchestrate it so someone can see the state.
- Don’t reach for Kafka when a queue suffices. A durable RabbitMQ queue handles most task-offload workloads; a log-based broker pays off for replay, multiple consumers, and retention — not for “send an email later.”
Decision Framework
| Need | Pattern | Protocol |
|---|---|---|
| Public API | REST | HTTP/JSON |
| Internal high-perf | gRPC | HTTP/2 + Protobuf |
| Fire-and-forget | Message Queue | AMQP/Kafka |
| Multiple consumers | Pub/Sub | Kafka/NATS |
| Cross-team decoupling | Event-Driven | Kafka + Outbox |
| Traffic control | API Gateway | HTTP + plugins |
| mTLS, retries, tracing | Service Mesh | Istio/Linkerd |
| Request aggregation | GraphQL | HTTP/JSON + schema |
Read the table as “start here, then verify against your constraints,” not as a flowchart. The row that matters most is the failure column from the earlier comparison: if the caller can tolerate the callee being down, async answers the question for you; if it can’t, pick the sync protocol and spend your effort on timeouts and circuit breakers instead of brokers.
Best Practices
- Prefer async for write-heavy workflows — decouples services, improves resilience
- Use the Outbox pattern — makes sure events are published with the DB transaction
- Make consumers idempotent — messages may be delivered more than once
- Set timeouts on sync calls — never let a caller hang indefinitely
- Use circuit breakers for sync calls — fail fast when a downstream service is down
- Version your events — consumers may not all upgrade simultaneously
- Use dead-letter queues — messages that fail processing go to DLQ for investigation
- Monitor end-to-end latency — async pipelines can accumulate latency across hops
- Keep events small — use the Claim Check pattern for large payloads
- Use schema registry — enforce event schema compatibility (Avro, Protobuf)
Common Mistakes
- Using REST for everything — tight coupling, cascading failures
- Not handling duplicate messages — idempotency is mandatory for async consumers
- Chaining synchronous calls deeply — latency compounds, failure probability rises
- Not using the Outbox pattern — dual-write to DB + broker is not atomic
- Ignoring message ordering — some events must be processed in order (e.g., order created before order cancelled)
- Not setting consumer concurrency limits — a slow consumer can exhaust resources
- Mixing sync and async for the same operation — pick one pattern per workflow
- Not monitoring queue depth — growing queues indicate consumer lag
See Also
Frequently Asked Questions
Should I use REST or gRPC for internal communication?
Use gRPC for internal service-to-service calls where performance matters. It comes with lower latency, smaller payloads, and strong typing. Use REST for public APIs, browser-facing endpoints, and integrations where HTTP/JSON interoperability is required.
What is the difference between a message queue and pub/sub?
In a message queue (point-to-point), each message is consumed by exactly one consumer. In pub/sub, each message is delivered to all subscribers. Use queues for task distribution (e.g., order processing). Use pub/sub for domain events (e.g., order created — inventory, shipping, and analytics all need to know).
How do I choose between sync and async for a workflow?
Ask what happens if the downstream service is down when the call arrives. If the user needs the answer now — a price check, a permission lookup — go synchronous and protect it with timeouts and a circuit breaker. If the work can complete later and the caller only needs confirmation it was accepted, go async. Mixed flows are normal: synchronous read for the response, event published for everything else.
What is a distributed monolith and how do I avoid it?
A system where services are deployed separately but can't function independently — every request chains through many of them synchronously. You avoid it by removing hops: denormalize read data, move non-blocking work onto events, and merge services that always change together. If a user action requires five services to be healthy at once, you've got one.
Do I need a service mesh?
A service mesh is useful when you've got many microservices (10+) and need consistent mTLS, traffic splitting, retries, and observability without modifying application code. For fewer services, libraries like resilience4j or Polly can handle retries and circuit breaking in-process.
Related Resources
Microservices Architecture — When to Use and When Not To
A practical guide to microservices: benefits, trade-offs, common patterns, and when to choose them over monoliths. Covers decomposition strategies and operational complexity.
GuideComplete Guide to Event-Driven Systems
Design event-driven backends: event sourcing, CQRS, sagas, outbox pattern, idempotency, eventual consistency, and production patterns.
GuidegRPC in Microservices — High-Performance RPC Guide
A practical guide to gRPC for microservices: Protocol Buffers, streaming, load balancing, and migration from REST for high-performance RPC.
PatternCircuit Breaker Pattern in Python, JavaScript, and Java
Prevent cascading failures by stopping requests to failing services. An architectural pattern for resilient distributed systems.
GuideComplete Guide to GraphQL Federation
Build unified GraphQL APIs across multiple services with Apollo Federation. Covers subgraphs, supergraph composition, entity resolution, and gateway deployment.
GuideComplete Guide to Kafka Stream Processing
Build real-time event pipelines with Kafka: producers, consumers, Kafka Streams, Connect, schema registry, and processing patterns.