Eager Loading Pattern: Fix the N+1 Problem
Load related data in a single query rather than multiple round-trips, preventing the N+1 problem and improving read performance.
Overview
The Eager Loading Pattern loads related data together with the primary entity in a single query, instead of issuing a separate query for every relationship. It prevents the N+1 problem: loading N entities and then firing N additional queries for their related data, for a total of N+1 database round-trips.
Most ORMs and data access layers support eager loading through SQL JOINs, batched IN queries, or subselects. The opposite approach, lazy loading, defers related data until the code actually touches it, which trades fewer upfront rows for more queries later.
When to Use
Use the Eager Loading Pattern when:
- You know in advance which relationships the caller will access, such as a list endpoint that always renders each item’s owner.
- The N+1 problem is measurable: query logs or a profiler show dozens of small lookups per request.
- Each item in a rendered list needs related data, so every fetched row would trigger at least one extra query.
- Network latency between the application and the database is high enough that round-trips dominate query time.
When to Avoid
- You only need related data for a small subset of entities; lazy loading fetches it on demand.
- The relationship holds large payloads (documents, images, JSON blobs) that most requests never read.
- Memory is tight and materializing the whole object graph at once is prohibitive.
- The JOIN is complex enough that it degrades the database more than several small, well-indexed queries would.
- You’re paginating a parent entity across a one-to-many join; see Eager Loading and Pagination below.
Solution
Python
from dataclasses import dataclass
from typing import List, Optional
import sqlite3

@dataclass
class Author:
    id: int
    name: str

@dataclass
class Book:
    id: int
    title: str
    author_id: int
    author: Optional[Author] = None

class BookRepository:
    def __init__(self, conn):
        self._conn = conn

    # N+1 Problem (BAD)
    def find_all_with_authors_naive(self) -> List[Book]:
        books = []
        for row in self._conn.execute("SELECT id, title, author_id FROM books"):
            book = Book(id=row["id"], title=row["title"], author_id=row["author_id"])
            # Additional query per book!
            author_row = self._conn.execute(
                "SELECT id, name FROM authors WHERE id = ?", (book.author_id,)
            ).fetchone()
            if author_row:
                book.author = Author(id=author_row["id"], name=author_row["name"])
            books.append(book)
        return books

    # Eager Loading (GOOD): single JOIN query
    def find_all_with_authors_eager(self) -> List[Book]:
        query = """
            SELECT b.id AS book_id, b.title, b.author_id,
                   a.id AS author_id, a.name AS author_name
            FROM books b
            JOIN authors a ON b.author_id = a.id
        """
        books = []
        for row in self._conn.execute(query):
            author = Author(id=row["author_id"], name=row["author_name"])
            book = Book(
                id=row["book_id"],
                title=row["title"],
                author_id=row["author_id"],
                author=author
            )
            books.append(book)
        return books

    # Batch loading: two queries, no JOIN
    def find_all_with_authors_batch(self) -> List[Book]:
        books = []
        rows = self._conn.execute("SELECT id, title, author_id FROM books").fetchall()
        author_ids = [r["author_id"] for r in rows]

        # Single query for all authors
        placeholders = ",".join("?" * len(author_ids))
        authors = {
            r["id"]: Author(id=r["id"], name=r["name"])
            for r in self._conn.execute(
                f"SELECT id, name FROM authors WHERE id IN ({placeholders})", author_ids
            )
        }

        for row in rows:
            book = Book(
                id=row["id"],
                title=row["title"],
                author_id=row["author_id"],
                author=authors.get(row["author_id"])
            )
            books.append(book)
        return books


# Setup
conn = sqlite3.connect(":memory:")
conn.row_factory = sqlite3.Row
conn.execute("CREATE TABLE authors (id INTEGER PRIMARY KEY, name TEXT)")
conn.execute("CREATE TABLE books (id INTEGER PRIMARY KEY, title TEXT, author_id INTEGER)")
conn.execute("INSERT INTO authors (name) VALUES ('Alice'), ('Bob')")
conn.execute("INSERT INTO books (title, author_id) VALUES ('Book A', 1), ('Book B', 1), ('Book C', 2)")

repo = BookRepository(conn)
books = repo.find_all_with_authors_eager()
for book in books:
    print(f"{book.title} by {book.author.name}")
Java
The classes below drop the public modifier so the whole example compiles as a single file (javac EagerLoading.java). In a real project each class would live in its own file.
import java.sql.*;
import java.util.*;

class Author {
    private final int id;
    private final String name;
    public Author(int id, String name) { this.id = id; this.name = name; }
    public int getId() { return id; }
    public String getName() { return name; }
}

class Book {
    private final int id;
    private final String title;
    private final int authorId;
    private Author author;

    public Book(int id, String title, int authorId) {
        this.id = id; this.title = title; this.authorId = authorId;
    }
    public int getId() { return id; }
    public String getTitle() { return title; }
    public Author getAuthor() { return author; }
    public void setAuthor(Author author) { this.author = author; }
}

class BookRepository {
    private final Connection conn;
    public BookRepository(Connection conn) { this.conn = conn; }

    public List<Book> findAllWithAuthors() throws SQLException {
        String query = """
            SELECT b.id AS book_id, b.title, b.author_id,
                   a.id AS author_id, a.name AS author_name
            FROM books b
            JOIN authors a ON b.author_id = a.id
            """;
        List<Book> books = new ArrayList<>();
        try (Statement stmt = conn.createStatement();
             ResultSet rs = stmt.executeQuery(query)) {
            while (rs.next()) {
                Author author = new Author(rs.getInt("author_id"), rs.getString("author_name"));
                Book book = new Book(rs.getInt("book_id"), rs.getString("title"), rs.getInt("author_id"));
                book.setAuthor(author);
                books.add(book);
            }
        }
        return books;
    }
}

// Usage
Connection conn = DriverManager.getConnection("jdbc:sqlite::memory:");
conn.createStatement().execute("CREATE TABLE authors (id INTEGER PRIMARY KEY, name TEXT)");
conn.createStatement().execute("CREATE TABLE books (id INTEGER PRIMARY KEY, title TEXT, author_id INTEGER)");
conn.createStatement().execute("INSERT INTO authors (name) VALUES ('Alice'), ('Bob')");
conn.createStatement().execute("INSERT INTO books (title, author_id) VALUES ('Book A', 1), ('Book B', 1), ('Book C', 2)");

BookRepository repo = new BookRepository(conn);
for (Book book : repo.findAllWithAuthors()) {
    System.out.println(book.getTitle() + " by " + book.getAuthor().getName());
}
JavaScript
The repository below runs against node:sqlite (built into Node ≥ 22.13), so the usage block actually executes instead of staying pseudocode.
const { DatabaseSync } = require('node:sqlite');

class Author {
  constructor(id, name) {
    this.id = id;
    this.name = name;
  }
}

class Book {
  constructor(id, title, authorId) {
    this.id = id;
    this.title = title;
    this.authorId = authorId;
    this.author = null;
  }
}

class BookRepository {
  constructor(db) {
    this.db = db;
  }

  // N+1 Problem (BAD)
  findAllWithAuthorsNaive() {
    const books = this.db.prepare('SELECT id, title, author_id FROM books').all()
      .map(r => new Book(r.id, r.title, r.author_id));
    for (const book of books) {
      const author = this.db.prepare('SELECT id, name FROM authors WHERE id = ?')
        .get(book.authorId);
      book.author = author ? new Author(author.id, author.name) : null;
    }
    return books;
  }

  // Eager Loading (GOOD)
  findAllWithAuthorsEager() {
    const rows = this.db.prepare(`
      SELECT b.id AS book_id, b.title, b.author_id,
             a.id AS author_id, a.name AS author_name
      FROM books b
      JOIN authors a ON b.author_id = a.id
    `).all();
    return rows.map(r => {
      const book = new Book(r.book_id, r.title, r.author_id);
      book.author = new Author(r.author_id, r.author_name);
      return book;
    });
  }

  // Batch Loading
  findAllWithAuthorsBatch() {
    const books = this.db.prepare('SELECT id, title, author_id FROM books').all()
      .map(r => new Book(r.id, r.title, r.author_id));
    const authorIds = [...new Set(books.map(b => b.authorId))];
    const authors = this.db.prepare(
      `SELECT id, name FROM authors WHERE id IN (${authorIds.join(',')})`
    ).all();
    const authorMap = new Map(authors.map(a => [a.id, new Author(a.id, a.name)]));

    for (const book of books) {
      book.author = authorMap.get(book.authorId) || null;
    }
    return books;
  }
}

// Usage
const db = new DatabaseSync(':memory:');
db.exec(`
  CREATE TABLE authors (id INTEGER PRIMARY KEY, name TEXT);
  CREATE TABLE books (id INTEGER PRIMARY KEY, title TEXT, author_id INTEGER);
  INSERT INTO authors (name) VALUES ('Alice'), ('Bob');
  INSERT INTO books (title, author_id) VALUES ('Book A', 1), ('Book B', 1), ('Book C', 2);
`);

const repo = new BookRepository(db);
for (const book of repo.findAllWithAuthorsEager()) {
  console.log(`${book.title} by ${book.author.name}`);
}
Explanation
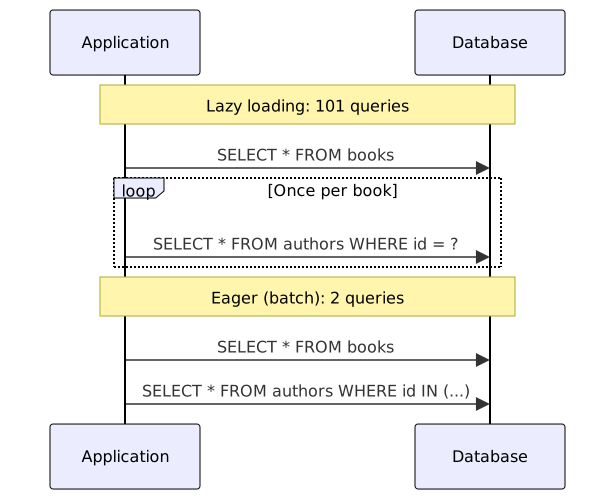
Loading 100 books the naive way costs 101 queries:
SELECT id, title, author_id FROM booksreturns the 100 books.SELECT id, name FROM authors WHERE id = ?runs once per book.
Eager loading collapses this into one round-trip with a JOIN:
SELECT b.id, b.title, b.author_id, a.id AS author_id, a.name
FROM books b
JOIN authors a ON b.author_id = a.id
or into two round-trips with batch loading: one query for the books, then WHERE id IN (...) for every referenced author at once.
Why ORMs mix JOIN and batch
JOIN isn’t a free win. Joining a parent to a single to-one relation (books -> authors) is safe because the row count stays flat. Joining across a to-many relation repeats the parent row once per child, and joining two to-many relations multiplies them: 100 books with 3 tags each already produce 300 result rows, and adding a second to-many join to reviews multiplies again.
That’s why mature ORMs apply different strategies per cardinality: they JOIN to-one relationships (select_related, Include, joinedload) and run a second batched IN query for to-many collections (prefetch_related, AsSplitQuery, selectinload). You get eager semantics without the cartesian product, and the row count of each result set stays proportional to the data you actually fetch.
Eager Loading and Pagination
Pagination interacts badly with JOINs on to-many relations. LIMIT applies to result rows, and a books JOIN chapters join repeats the book row once per chapter, so LIMIT 10 can return as few as two or three books.
Every major ORM solves this the same way: it ignores the join for the page query, paginates the parents, and then fetches the collection with a batched IN query keyed by those parent IDs. Hibernate warns about exactly this when you combine setMaxResults with a collection fetch: “firstResult/maxResults specified with collection fetch; applying in memory”. The in-memory fallback works, but it silently loads the entire un-paginated join into the JVM first.
Detecting the N+1 Problem in Practice
N+1 rarely shows up in a single slow query; it shows up as query count. Concrete ways to see it:
- Django:
assertNumQueries(3)inside a test, or Django Debug Toolbar in development, shows every statement per request. - Hibernate / JPA:
hibernate.generate_statistics=truereports per-session query counts; a session executing hundreds of selects is a red flag. - SQLAlchemy:
create_engine(url, echo=True)logs every SQL statement during development. - Prisma / Node: subscribe to the
queryevent (prisma.$on('query', ...)) and loge.durationper statement. - PostgreSQL in production:
pg_stat_statementssurfaces the same author lookup executed tens of thousands of times per hour, which no amount of indexing fixes.
Variants
| Variant | Mechanism | Use Case |
|---|---|---|
| JOIN | Single SQL JOIN query | To-one relationships, small to medium datasets |
| Batch / IN clause | Two queries with an IN list | To-many collections, paginated parents, avoiding cartesian products |
| Subselect | Correlated subquery for related data | Databases where the optimizer handles subselects better than wide joins |
| GraphQL DataLoader | Batches and deduplicates per request | APIs with dynamic query shapes; see DataLoader batching |
What Works
- Measure before optimizing. Assert on query count (
assertNumQueries, Hibernate statistics, anecholog) so you fix a proven N+1 rather than a guessed one. - JOIN to-one, batch to-many. This mirrors what ORMs do internally and avoids the cartesian products that make joined collection fetches expensive.
- Select only the columns you need.
SELECT *on a join pulls every column of both tables; name the fields the caller actually reads. - Choose the fetch plan per use case. A detail view and a bulk export need different object graphs; most ORMs let you pick the strategy per query instead of per entity.
- Watch memory on large graphs. Eager loading a deep graph can materialize thousands of objects; batch and paginate instead.
Common Mistakes
- Eager loading everything by default. Marking every relationship as eager builds massive object graphs nobody asked for.
- Lazy loading inside a loop. Iterating entities and touching
book.authorper element is exactly how N+1 happens. - Ignoring cartesian products. Joining two to-many relationships multiplies rows; the result set grows quadratically, not linearly.
- Joining a to-many collection while paginating.
LIMITcounts joined rows, not parents, so pages come back incomplete or the ORM falls back to in-memory pagination. - Assuming JOIN always wins. For large datasets or distant tables, two indexed queries can beat one wide join; measure both.
Real-World Examples
Django ORM
Book.objects.select_related('author') emits a JOIN for to-one relationships, while prefetch_related('tags') issues a second query for to-many relations and stitches the results in Python. See the Django queryset documentation.
SQLAlchemy
session.query(Book).options(joinedload(Book.author)) produces the JOIN, and selectinload(Book.tags) produces the batched IN query. The same join-to-one, batch-to-many split; see the SQLAlchemy relationship loading docs.
Entity Framework Core
.Include(b => b.Author) joins to-one relationships. Since EF Core 5, .AsSplitQuery() splits to-many includes into separate queries, avoiding the duplicate parent rows a single join would produce. See the EF Core eager loading docs.
Rails Active Record
Book.includes(:author) picks between preload (a separate batched query) and eager_load (a LEFT JOIN) depending on whether the query filters on the association. See the Rails querying guide.
Prisma
prisma.book.findMany({ include: { author: true } }) resolves relations with batched queries rather than a join, which is why Prisma avoids N+1 without exposing a fetch-strategy API.
GraphQL DataLoader
DataLoader batches and deduplicates identical field loads across parent objects per request, solving N+1 at the resolver layer instead of the ORM layer. The DataLoader batching recipe shows a working implementation.
See Also
- Runnable companion repository — the Python, JavaScript, and Java examples from this page as executable files.
- Lazy loading for images, components, and data — the deferral counterpart, applied to frontend resources.
- SQL query optimization guide — indexing and plan analysis for when eager loading alone isn’t enough.
Frequently Asked Questions
What is the N+1 problem?
Loading N entities and then issuing one extra query per entity for related data, producing N+1 queries where one or two would suffice. It appears whenever code iterates a collection and touches a lazily-loaded relationship inside the loop.
When should I choose batch loading over a JOIN?
Choose batch loading for to-many collections, for paginated parents, and whenever a join would produce a cartesian product. Choose a JOIN for to-one relationships and small result sets where one round-trip is cheapest.
Does eager loading work with pagination?
Only with care. Joining a to-many collection and applying LIMIT counts joined rows, not parents, so pages return fewer parents than expected. ORMs handle it by paginating parents first and batch-loading the collection afterwards.
Is eager loading always better than lazy loading?
No. Eager loading wins when you know you will use the data; lazy loading wins when the data is optional, large, or only needed for a subset of rows. The wrong default in either direction wastes either queries or memory.
How do I detect N+1 queries in production?
Watch query counts, not query latency. Enable per-request query logging (Hibernate statistics, SQLAlchemy echo, a Prisma query listener) or check pg_stat_statements for identical lookups executed thousands of times.
Related Resources
Data Mapper Pattern: Keep Domain Models DB-Free
Separate in-memory domain objects from the database by delegating persistence to a dedicated mapper layer, keeping models framework-agnostic.
PatternIdentity Map Pattern
Cache objects by primary key so each database row maps to a single in-memory instance per transaction. No duplicate objects, no lost updates.
RecipeImplement Lazy Loading for Images, Components, and Data
How to defer loading of non-critical resources until they are needed, improving initial page load time, reducing bandwidth, and optimizing Core Web Vitals.
RecipeBatch and Cache Database Queries with GraphQL DataLoader
Use DataLoader to coalesce individual load requests into batched database calls, solving the N+1 query problem in GraphQL resolvers
GuideComplete Guide to SQL Query Optimization
Find and fix slow SQL queries: read EXPLAIN plans, index the right way, kill N+1 queries, and apply partitioning, pooling, and caching on PostgreSQL and MySQL.