Build a Slack Bot with OpenAI: Mentions, DMs, Memory
A conversational Slack bot powered by OpenAI that answers mentions and direct messages, keeps per-user conversation history, and stays under budget
Overview
Plug an LLM into Slack and it can answer questions, summarize threads, and run commands right where your team already talks. This recipe wires Slack Bolt’s Socket Mode (no public URL needed) to the OpenAI chat completions API, with per-user conversation memory, threaded replies, and direct messages. For a general chatbot without Slack, see Chatbot with OpenAI.
When to Use
- You want an assistant inside Slack that already knows your team’s context.
- The same questions keep coming up in public channels and you want them answered automatically.
- You’d rather test a conversational interface in chat than build a UI first.
- Don’t point it at every message in busy channels — without filtering and per-user rate limits, the OpenAI bill will surprise you.
Prerequisites
- A Slack app with a Bot Token and Socket Mode enabled (you’ll get
xoxb-andxapp-tokens). - An OpenAI API key.
- Node.js 18+ or Python 3.10+.
Solution
Node.js
npm install @slack/bolt openai dotenv# .env
SLACK_BOT_TOKEN=xoxb-your-bot-token
SLACK_SIGNING_SECRET=your-signing-secret
SLACK_APP_TOKEN=xapp-your-app-token
OPENAI_API_KEY=sk-your-openai-key// app.js
import { App } from '@slack/bolt';
import OpenAI from 'openai';
import dotenv from 'dotenv';
dotenv.config();
const slack = new App({
token: process.env.SLACK_BOT_TOKEN,
signingSecret: process.env.SLACK_SIGNING_SECRET,
appToken: process.env.SLACK_APP_TOKEN,
socketMode: true,
});
const openai = new OpenAI({ apiKey: process.env.OPENAI_API_KEY });
// In-memory conversation store (use Redis in production)
const conversations = new Map();
function getHistory(userId) {
if (!conversations.has(userId)) {
conversations.set(userId, [{ role: 'system', content: 'You are a helpful assistant in a Slack workspace.' }]);
}
return conversations.get(userId);
}
async function getGPTResponse(messages) {
const response = await openai.chat.completions.create({
model: 'gpt-4o-mini',
messages,
max_tokens: 500,
});
return response.choices[0].message.content;
}
// Respond to app mentions in channels
slack.event('app_mention', async ({ event, say }) => {
const text = event.text.replace(/<@[^>]+>/, '').trim();
if (!text) return; // bare mention with no question
const history = getHistory(event.user);
history.push({ role: 'user', content: text });
const reply = await getGPTResponse(history);
history.push({ role: 'assistant', content: reply });
// Keep the system prompt plus the last 10 messages
if (history.length > 11) {
conversations.set(event.user, [history[0], ...history.slice(-10)]);
}
await say({ text: reply, thread_ts: event.ts });
});
// Respond to direct messages — skip bots, non-DM traffic, and empty text
slack.message(async ({ message, say }) => {
if (message.bot_id || message.subtype || message.channel_type !== 'im' || !message.text?.trim()) {
return;
}
const history = getHistory(message.user);
history.push({ role: 'user', content: message.text });
const reply = await getGPTResponse(history);
history.push({ role: 'assistant', content: reply });
await say(reply);
});
(async () => {
await slack.start();
console.log('Slack bot is running');
})();node app.jsPython
pip install slack-bolt openai python-dotenv# bot.py
import os
from slack_bolt import App
from slack_bolt.adapter.socket_mode import SocketModeHandler
from openai import OpenAI
from dotenv import load_dotenv
load_dotenv()
app = App(token=os.environ["SLACK_BOT_TOKEN"])
openai_client = OpenAI(api_key=os.environ["OPENAI_API_KEY"])
conversations = {}
def get_history(user_id):
if user_id not in conversations:
conversations[user_id] = [
{"role": "system", "content": "You are a helpful assistant in a Slack workspace."}
]
return conversations[user_id]
def get_gpt_response(messages):
response = openai_client.chat.completions.create(
model="gpt-4o-mini",
messages=messages,
max_tokens=500,
)
return response.choices[0].message.content
@app.event("app_mention")
def handle_mention(event, say):
import re
text = re.sub(r"<@[^>]+>", "", event["text"]).strip()
if not text:
return # bare mention with no question
history = get_history(event["user"])
history.append({"role": "user", "content": text})
reply = get_gpt_response(history)
history.append({"role": "assistant", "content": reply})
if len(history) > 11:
conversations[event["user"]] = [history[0]] + history[-10:]
say(text=reply, thread_ts=event["ts"])
@app.message("")
def handle_dm(message, say):
# Skip bots, non-DM traffic, and empty text
if message.get("bot_id") or message.get("subtype") or message.get("channel_type") != "im":
return
if not message.get("text", "").strip():
return
history = get_history(message["user"])
history.append({"role": "user", "content": message["text"]})
reply = get_gpt_response(history)
history.append({"role": "assistant", "content": reply})
say(reply)
if __name__ == "__main__":
handler = SocketModeHandler(app, os.environ["SLACK_APP_TOKEN"])
handler.start()How It Works
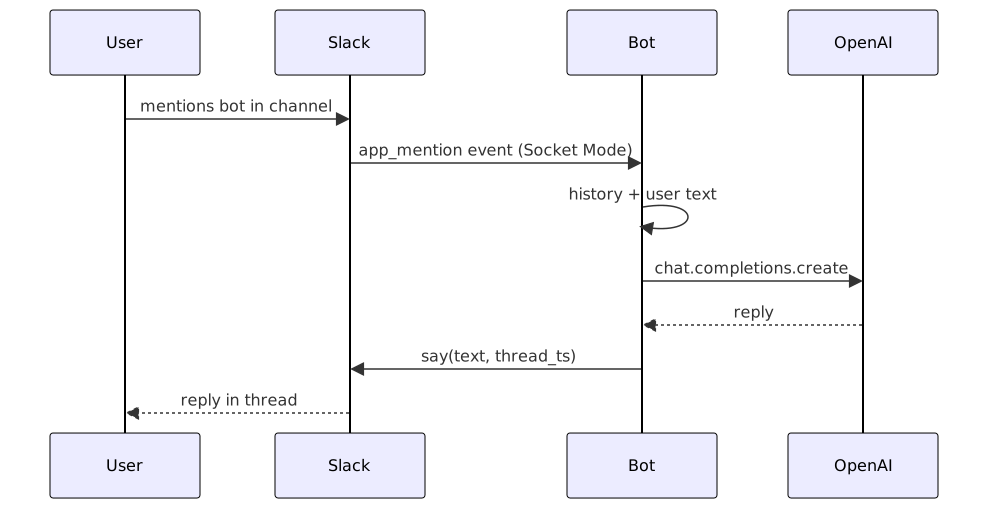
- Socket Mode: the bot opens a WebSocket connection to Slack, so it runs behind a firewall without a public endpoint. Bolt acknowledges events for you — that matters because Slack retries anything not acked within ~3 seconds.
- Conversation memory: each user gets a rolling window (system prompt + last 10 messages). A
Map/dictlives and dies with the process — use Redis for anything real. - Threading: channel replies pass
thread_ts, so answers stay attached to the triggering message instead of flooding the channel. - Direct messages: DMs get a separate handler with
bot_id/subtype/empty-text guards so the bot can’t loop on its own replies.
Variants
| Variant | When to pick it |
|---|---|
| Node.js + Socket Mode | Default; runs anywhere without a public URL |
Python + SocketModeHandler | Same flow for Python shops (slack-bolt + openai) |
| HTTP events endpoint | When you already expose a public URL and prefer request/response over a persistent socket |
| Thread summarizer | Listen for thread events and offer TL;DR replies on demand |
| Vision input | Forward uploaded images to a vision-capable model (e.g., gpt-4o) |
What Works
- Swap the in-memory store for Redis on multi-instance deployments — a restart otherwise wipes every conversation. See API Rate Limiting with Redis for Redis patterns.
- Truncate by tokens, not messages. Ten long messages can blow the context window; count tokens with
tiktokeninstead of a fixed “last 10”. - Cap spend per user. One user hammering the bot can burn the whole OpenAI budget — enforce a daily request or token quota per user ID.
- Retry OpenAI calls with backoff. Rate limits and transient network errors are normal; wrap the call like in Retry Logic with Exponential Backoff.
- Log every interaction: who asked, where, when, and how many tokens it used. You need it for cost audits and for debugging weird answers.
- Expose a
/healthendpoint when the bot runs as a service, so monitoring can tell “bot down” from “Slack down”. - Filter before you spend. Check
bot_id, subtype and empty text before calling OpenAI — filtering after the API call still costs tokens.
Common Mistakes
- Acknowledging late — Slack retries any event not acked within ~3 seconds, so you answer the same message twice. Bolt acks for you; on a custom endpoint, ack first and process async.
- Checking
.envfiles or tokens into git — keep keys in environment variables or a secrets manager, never in code. - Not filtering the bot’s own messages — check
message.bot_idand skip it, or the bot answers itself forever. - Ignoring thread context — a follow-up inside a thread needs the earlier messages; fetch them with Slack’s
conversations.repliesAPI. - Calling the API without
max_tokens— an unbounded answer can eat the budget in one call. - Responding to empty text or bare mentions — validate
message.textbefore spending tokens. - Forgetting Slack’s own rate limit (~1 message per second per channel) — queue or batch replies on busy channels.
Production Checklist
- API keys in environment variables, not in code
- Bot filters
bot_id, subtypes, and empty messages - Conversation history persisted in Redis or Postgres (not in-memory)
- Per-user rate limits (max requests or tokens per day)
- OpenAI calls have a timeout and retry with backoff
- Token usage logged per request for cost monitoring
- Errors shown to users are friendly (no raw API errors)
- Channel replies posted in threads
-
/healthendpoint exposed for monitoring - Structured logs with correlation IDs for debugging
See Also
- Slack API — Socket Mode — event delivery without a public URL.
- Slack API — conversations.replies — fetch thread history for context.
- OpenAI API Reference — chat completions parameters and the
usagefield. - Companion repository — runnable
app.js,bot.py, and.env.example.
Frequently Asked Questions
How much does this cost to run?
gpt-4o-mini costs roughly $0.15 per 1M input tokens and $0.60 per 1M output tokens, so a short exchange lands well under a cent. Read the usage field on every response and alert when daily spend passes your threshold.
Can the bot see channel history?
Only with the channels:history scope, and only messages posted after it joined. Check your company's privacy policy first — the bot stores whatever it reads.
How do I add thread context to the bot's answers?
Call conversations.replies with the thread's ts, take the last 5–10 messages, and prepend them to the messages array. Without it, the bot answers each thread message in isolation.
How do I restrict the bot to specific channels?
Keep an allowlist of channel IDs in config or env vars; when event.channel isn't on it, return early.
Can I use function calling with the Slack bot?
Yes — declare tools like search_knowledge_base in the OpenAI request, run the function when the model returns a tool call, then feed the result back for a second completion. See AI Agents with Tool Use.
How do I deploy this to production?
Package it as a Docker container and run it on ECS, Kubernetes, or a VPS under pm2/systemd. Socket Mode needs no inbound ports; add a health check and auto-restart and you're done.
How do I handle many users messaging at once?
Socket Mode pushes events concurrently, but a slow OpenAI call blocks that user's next request. Queue per user or run a small worker pool so one long conversation can't stall the rest.
Related Resources
OpenAI Assistants API Chatbot: Build, Cost & Deploy
How to create an AI chatbot using the OpenAI Assistants API with function calling and file search.
RecipeAI Agents with Tool Use: ReAct in Practice
Build autonomous AI agents that can use external tools and APIs to accomplish complex tasks.
RecipeImplement API Rate Limiting with Redis
Protect APIs from abuse with Redis-backed token bucket and sliding window limiters, including burst handling and distributed coordination
RecipeBuild a RAG Pipeline with LangChain and Vector Databases
How to build a Retrieval-Augmented Generation (RAG) pipeline using LangChain and vector databases for AI-powered search