OpenTelemetry Guide: Traces, Metrics and Logs
A practical guide to OpenTelemetry in production: instrumentation, collectors, sampling strategies, and wiring OTLP to Jaeger, Prometheus, and Grafana.
Overview
You instrument your application once and the telemetry can flow to any backend that speaks OTLP: Jaeger, Tempo, Prometheus, Grafana, Datadog, New Relic, or a cloud provider’s native service. That is the pitch of OpenTelemetry (OTel), the vendor-neutral observability framework born from the merger of OpenTracing and OpenCensus under the CNCF, covering all three signals: traces, metrics, and logs.
This guide walks through the pieces that matter in production. It covers how the SDK and the Collector fit together, what correct instrumentation code looks like, how to configure a Collector pipeline, and the decisions teams get wrong most often: sampling, resource attributes, and deployment topology. If you’re looking for the broader observability picture first, Observability — Metrics, Logs, and Traces Complete Guide is a good starting point; this guide assumes you already know why you want telemetry and focuses on getting OTel running well.
In practice each signal answers a different question. Traces tell you where a request spent its time across services. Metrics tell you aggregates over time: error rates, latency percentiles, saturation. Logs give you the event-level detail behind a specific failure. OTel’s real contribution is correlating all three, so a trace ID on a log line takes you straight from an alert to the exact request that failed.
When to Use
- You want instrumentation that outlives your current observability backend, so a vendor change doesn’t mean re-instrumenting every service.
- You need traces, metrics, and logs from the same application with one shared context.
- You’re migrating between observability vendors, or evaluating several.
- You run polyglot services (Go, Java, Python, Node.js, .NET) and want one instrumentation model instead of five.
- You need to collect telemetry from services you can’t modify, through the Collector’s receivers.
Skip it when you’ve got a single service and a working vendor agent: OTel adds an SDK plus a Collector to operate, and for a trivial setup the payoff is small. The moment a second team or service joins, the standardization argument wins.
Architecture
Three layers do the work in an OpenTelemetry deployment:

| Component | Role |
|---|---|
| API | The instrumentation surface your code calls. Stable first, before the SDK, so libraries can instrument safely. |
| SDK | The implementation that creates, samples, buffers, and exports telemetry from your process. |
| Collector | A standalone service that receives OTLP, processes it, and exports it to backends. |
| OTLP | The wire protocol. gRPC on port 4317 or HTTP/protobuf on 4318. |
| Semantic conventions | Standard attribute names (http.request.method, db.system, service.name) so every tool reads the same data. |
Applications can export directly to a backend, but in production almost everything flows through a Collector. The Collector decouples your app from the backend choice, absorbs spikes, and centralizes concerns like batching, retries, and sensitive-data filtering.
Instrumenting an Application
Auto-instrumentation
Auto-instrumentation is the fastest way to get useful data — the Python tracing recipe walks a minimal setup. For Python, the distro package detects installed frameworks and patches them at startup:
pip install opentelemetry-distro opentelemetry-exporter-otlp
opentelemetry-bootstrap -a installOTEL_SERVICE_NAME=my-service \
OTEL_EXPORTER_OTLP_ENDPOINT=http://collector:4317 \
OTEL_TRACES_EXPORTER=otlp \
OTEL_METRICS_EXPORTER=otlp \
OTEL_LOGS_EXPORTER=otlp \
opentelemetry-instrument python myapp.pyThe environment variables are part of the spec and work the same in every SDK. OTEL_SERVICE_NAME sets service.name on the resource, OTEL_EXPORTER_OTLP_ENDPOINT points to your Collector or backend, and the three *_EXPORTER variables pick the exporter per signal.
Manual instrumentation
The common mistake in manual setup is creating exporters but never attaching them to the providers. A TracerProvider without a span processor drops every span silently. A complete, working Python setup looks like this:
from opentelemetry import trace, metrics
from opentelemetry.sdk.resources import Resource
from opentelemetry.sdk.trace import TracerProvider
from opentelemetry.sdk.trace.export import BatchSpanProcessor
from opentelemetry.sdk.metrics import MeterProvider
from opentelemetry.sdk.metrics.export import PeriodicExportingMetricReader
from opentelemetry.exporter.otlp.proto.grpc.trace_exporter import OTLPSpanExporter
from opentelemetry.exporter.otlp.proto.grpc.metric_exporter import OTLPMetricExporter

resource = Resource.create({
    "service.name": "checkout-api",
    "service.version": "1.4.2",
    "deployment.environment.name": "production",
})

# Traces: provider -> processor -> exporter
provider = TracerProvider(resource=resource)
provider.add_span_processor(BatchSpanProcessor(OTLPSpanExporter()))
trace.set_tracer_provider(provider)
tracer = trace.get_tracer(__name__)

# Metrics: provider -> reader -> exporter
reader = PeriodicExportingMetricReader(OTLPMetricExporter())
meter_provider = MeterProvider(resource=resource, metric_readers=[reader])
metrics.set_meter_provider(meter_provider)
meter = metrics.get_meter(__name__)

request_counter = meter.create_counter("http_requests_total")

with tracer.start_as_current_span("handle_request") as span:
    span.set_attribute("http.request.method", "GET")
    span.set_attribute("http.route", "/api/users")
    request_counter.add(1, {"method": "GET", "route": "/api/users"})
Two details matter here. First, always use BatchSpanProcessor in production; the synchronous SimpleSpanProcessor exports on every span and blocks your application threads. Second, build the Resource once and attach it to every provider, so all signals carry the same service identity.
For Node.js, the equivalent entry point is NodeSDK from @opentelemetry/sdk-node, which wires exporters and auto-instrumentations in one object. The advanced section below has a full example.
The Collector
The Collector is a vendor-agnostic process built around pipelines: receivers accept telemetry, processors transform it, and exporters send it out. You define a pipeline per signal and share receivers across them.
# otel-collector-config.yaml
receivers:
  otlp:
    protocols:
      grpc:
        endpoint: 0.0.0.0:4317
      http:
        endpoint: 0.0.0.0:4318

processors:
  batch:
    timeout: 1s
    send_batch_size: 1024

exporters:
  prometheusremotewrite:
    endpoint: http://mimir:9009/api/v1/push
  otlp/jaeger:
    endpoint: jaeger:4317
    tls:
      insecure: true
  otlphttp/loki:
    endpoint: http://loki:3100/otlp

service:
  pipelines:
    traces:
      receivers: [otlp]
      processors: [batch]
      exporters: [otlp/jaeger]
    metrics:
      receivers: [otlp]
      processors: [batch]
      exporters: [prometheusremotewrite]
    logs:
      receivers: [otlp]
      processors: [batch]
      exporters: [otlphttp/loki]
A few things in this config are worth calling out because older examples get them wrong:
- The dedicated
lokiexporter was deprecated and removed from the contrib distribution. Loki 3.x accepts OTLP natively, so useotlphttppointed at its/otlpendpoint. prometheusremotewritepushes metrics to a remote write endpoint. If your Prometheus scrapes instead, use theprometheusexporter, which exposes a/metricsendpoint on the Collector.tls.insecure: trueis fine for a local Jaeger. In production, configure real TLS or run the Collector behind a service mesh that handles mTLS.
Agent vs. gateway topology
Most production deployments use both roles:
| Role | Deployment | Job |
|---|---|---|
| Agent | DaemonSet or sidecar, one per node | Receive telemetry locally, add host metadata, forward upstream quickly |
| Gateway | Deployment or standalone service | Aggregate, filter, sample, and export to backends |
Apps send to their node’s agent, which forwards to the gateway cluster. This pattern keeps app-side latency low, isolates export failures, and gives you one place to apply sampling and filtering policies. A single gateway also works for small setups; an agent-only deployment makes sense when the backend is trivially reachable.
Sampling Strategies
Sampling decides which traces to keep, and it’s where most OTel rollouts either save or burn money.
Head sampling makes the decision at the span’s start, inside the SDK. It’s cheap but blind: you keep a random 10% of everything, including boring successful requests. Configure it with environment variables:
OTEL_TRACES_SAMPLER=parentbased_traceidratio \
OTEL_TRACES_SAMPLER_ARG=0.1
Tail sampling makes the decision in the Collector after seeing the whole trace. You can keep all errors and slow requests while sampling only a fraction of healthy traffic:
processors:
  tail_sampling:
    decision_wait: 10s
    policies:
      - name: errors
        type: status_code
        status_code:
          status_codes: [ERROR]
      - name: slow-traces
        type: latency
        latency:
          threshold_ms: 2000
      - name: baseline
        type: probabilistic
        probabilistic:
          sampling_percentage: 10
Tail sampling requires a Collector deployment where all spans of a trace land on the same instance, which is what the gateway topology gives you. decision_wait controls how long the Collector holds a trace before deciding; longer waits capture complete traces at the cost of memory.
| Head sampling | Tail sampling | |
|---|---|---|
| Decision point | SDK, at span start | Collector, after the trace completes |
| Sees request outcome | No | Yes (errors, latency, attributes) |
| Infrastructure cost | None | Collector memory for buffering |
| Typical use | High-volume services, rough control | Keeping every error while sampling healthy traffic |
A common setup mixes both: a low head-sampling ratio on very hot services to protect the Collector, plus tail policies that guarantee errors and outliers are never dropped.
Resource Attributes and Semantic Conventions
Resource attributes describe what produced the telemetry: service name, version, environment, host, cloud region, Kubernetes namespace. They’re the difference between “error rate spiked” and “error rate spiked in checkout-api v1.4.2 in eu-west-1”.
Set the obvious ones on the SDK resource (as in the instrumentation example) and let the Collector enrich the rest:
processors:
  resourcedetection:
    detectors: [env, system, docker, k8snode]
    timeout: 5s
Semantic conventions standardize attribute names across the ecosystem: http.request.method, db.system, messaging.destination.name. Follow them and every dashboard, alert, and backend query works the same regardless of language. Inventing your own names is how you end up with http.method on one service and http_method on another.
Context Propagation
OpenTelemetry propagates trace context across service boundaries with W3C Trace Context headers:
traceparent: 00-0af7651916cd43dd8448eb211c80319c-b7ad6b7169203331-01
tracestate: vendor=value
The traceparent header carries the trace ID, the parent span ID, and sampling flags. tracestate holds vendor-specific data. With propagation working, a request that starts in a JavaScript frontend continues through Node.js, Python, and Go backends as one trace. Most instrumented HTTP clients inject the headers automatically; if you publish to a queue or call an uninstrumented service, you may need to inject and extract context manually with the propagators in your SDK.
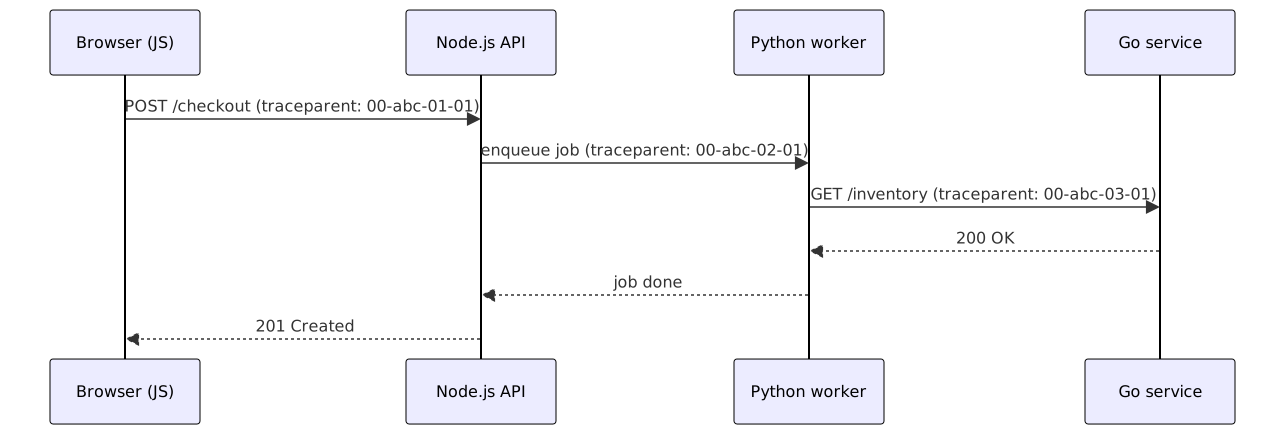
The trace ID (abc above, shortened) stays identical end to end; only the parent span ID changes per hop.
baggage is a separate header for propagating key-value pairs (tenant ID, experiment variant) alongside the trace. Keep it small: it travels on every request.
Logs: Bridging What You Already Have
OTel logs are the youngest signal, and most apps already emit logs through a mature library. You rarely need to rewrite logging code. The practical approach is bridging: SDK log appenders attach trace context (trace ID, span ID) to each record, and the Collector ingests either OTLP logs or files via the filelog receiver. Once log records carry the trace context, your backend can jump from a trace to its exact log lines and back, which is where the real debugging value shows up. If your stack already runs Fluent Bit or a similar agent, it can stay: send its output to the same backends and let the Collector handle the OTLP-native services.
For apps that only write to a log file, a filelog receiver tails it directly:
receivers:
  filelog:
    include: [ /var/log/app/*.log ]
    operators:
      - type: json_parser
      - type: trace_parser
        trace_id:
          parse_from: attributes.trace_id
        span_id:
          parse_from: attributes.span_id
service:
  pipelines:
    logs:
      receivers: [filelog]
      exporters: [otlphttp]
The trace_parser operator is the piece that matters: it lifts trace_id/span_id fields out of each JSON record and turns them into real correlation, no code changes required. For libraries with OTel-native appenders (log4j, pino, zap), skip the file entirely and send OTLP logs straight to the Collector. Either way, the payoff is the same: click a slow span, land on the exact log lines it produced.
Advanced: Full Instrumentation Example (Node.js)
Putting it together, here’s an e-commerce service with auto-instrumentation plus custom spans and metrics around a checkout flow:
import { NodeSDK } from "@opentelemetry/sdk-node";
import { getNodeAutoInstrumentations } from "@opentelemetry/auto-instrumentations-node";
import { OTLPTraceExporter } from "@opentelemetry/exporter-trace-otlp-grpc";
import { PrometheusExporter } from "@opentelemetry/exporter-prometheus";
import { trace, metrics, SpanStatusCode } from "@opentelemetry/api";

const sdk = new NodeSDK({
  traceExporter: new OTLPTraceExporter({ url: "http://otel-collector:4317" }),
  metricReader: new PrometheusExporter({ port: 9464 }),
  instrumentations: [getNodeAutoInstrumentations({
    "@opentelemetry/instrumentation-fs": { enabled: false },
  })],
});
sdk.start();

const tracer = trace.getTracer("ecommerce-api");
const meter = metrics.getMeter("ecommerce-api");

const checkoutCounter = meter.createCounter("checkouts.total", {
  description: "Total checkouts processed",
});
const checkoutDuration = meter.createHistogram("checkout.duration", {
  description: "Checkout duration in ms",
  unit: "ms",
});

async function checkout(cart) {
  const started = Date.now();
  return tracer.startActiveSpan("checkout", async (span) => {
    span.setAttribute("cart.items", cart.items.length);
    try {
      const validation = await tracer.startActiveSpan("validate_cart",
        async (child) => {
          try {
            const result = validateCart(cart);
            child.setAttribute("cart.valid", result.valid);
            return result;
          } finally {
            child.end();
          }
        });

      const payment = await tracer.startActiveSpan("process_payment",
        async (child) => {
          try {
            const result = await processPayment(cart);
            child.setAttribute("payment.status", result.status);
            return result;
          } finally {
            child.end();
          }
        });

      span.setStatus({ code: SpanStatusCode.OK });
      checkoutCounter.add(1, { status: "success", method: cart.paymentMethod });
      checkoutDuration.record(Date.now() - started, { status: "success" });
      return { validation, payment };
    } catch (error) {
      span.recordException(error);
      span.setStatus({ code: SpanStatusCode.ERROR, message: error.message });
      checkoutCounter.add(1, { status: "error" });
      throw error;
    } finally {
      span.end();
    }
  });
}
Two habits make this example production-shaped rather than demo-shaped. Child spans end inside finally so a throwing step doesn’t leak unfinished spans, and status codes come from SpanStatusCode instead of magic numbers. Custom metrics record the business dimension (payment method, outcome), which is what you actually alert and dashboard on later.
Deploying in Production
On Kubernetes, the standard deployment is a DaemonSet agent plus a Deployment gateway. The OpenTelemetry Operator can manage both and can also inject auto-instrumentation into pods via annotations like instrumentation.opentelemetry.io/inject-nodejs: "true", which removes the need to touch application manifests at all. The Operator also owns the Instrumentation custom resource, where you pin SDK images, exporter endpoints, and resource attributes centrally instead of repeating them in every deployment.
Outside Kubernetes, the Collector ships as a single binary or container and runs fine as a systemd unit or a small VM deployment; the same pipeline configuration applies.
What Works
Practical points that bite teams later:
- HA: run at least two gateway replicas behind a service. A single Collector is a single point of failure for all telemetry.
- Cardinality: metrics with unbounded label values (user IDs, request paths) explode storage and cost. Keep label values bounded and normalize routes (
/api/users/{id}, not/api/users/42). - Buffering: the
batchprocessor smooths spikes. For durability, persistent queues (file_storageextension) survive Collector restarts. - Cost control: every signal has egress and storage cost. Tail sampling on traces, dropping noisy logs at the Collector, and reducing metric cardinality are the three big levers. Measure them early, not when the first big invoice lands.
Migrating from Vendor Agents
If you’re on a Jaeger client, Zipkin instrumentation, or a proprietary agent, the migration path is incremental. Replace the vendor SDK with the OTel SDK; the data model maps cleanly because OTel absorbed the earlier projects’ semantics. Keep the existing backend during the transition: Jaeger accepts OTLP natively, so otlp/jaeger exports keep traces looking identical in the Jaeger UI while you migrate service by service. For instrumentation you can’t rewrite, the Collector’s zipkin, jaeger, and statsd receivers let old agents send to OTel pipelines unchanged.
For tracing-specific depth, Distributed Tracing Complete Guide covers span design, trace analysis, and debugging workflows in more detail.
Common Mistakes
- Forgetting to flush on shutdown: unflushed spans and metrics vanish when a pod terminates. Call
shutdown/forceFlushon the providers, and give containers aterminationGracePeriodSecondsthat lets the flush complete. - Exporting everything synchronously:
SimpleSpanProcessor(or the equivalent) exports per span and stalls request threads. Always batch. - Skipping resource attributes: without
service.nameanddeployment.environment.name, every signal is an anonymous blob you can’t filter by. - A single Collector for everything: one gateway with no agent and no replicas becomes a bottleneck and a single point of failure.
- Leaving default sampling: the default
parentbased_always_onkeeps 100% of traces, which is fine in dev and expensive at scale. - High-cardinality metrics: putting user IDs or raw URLs in metric labels is the fastest way to blow up your metrics bill.
Troubleshooting
- No spans reach the backend: check the OTLP endpoint and port (4317 gRPC vs 4318 HTTP), then TLS.
tls.insecure: trueagainst a TLS-enabled endpoint fails quietly in some SDK versions. - Collector OOMKilled: unbounded
batchgrowth plus high throughput exhausts memory. Lowersend_batch_size, add replicas, and check for a tail_samplingdecision_waitthat’s too long for your traffic. - Metrics arrive but traces don’t: the pipelines are separate in
service.pipelines. A missing entry undertraces:means the Collector silently drops them. - Duplicate or missing attributes: two
resourcedetectiondetectors disagreeing, or attributes set on spans instead of the resource. Resource attributes live once per service; span attributes live per operation. - Sampling doesn’t match expectations: head sampling decided in the SDK can’t be re-decided downstream. If the gateway shows ~100% of traces, check
OTEL_TRACES_SAMPLERfirst.
Further Reading
- Companion resources: the Collector pipeline, a runnable Python instrumentation script, and a docker-compose stack with Jaeger from this guide.
- OpenTelemetry documentation: the official reference for concepts, SDKs, and the Collector.
- OTLP specification: the wire protocol details.
- opentelemetry-collector-contrib: the full catalog of receivers, processors, and exporters.
- Semantic conventions: the standard attribute names used across all signals.
- W3C Trace Context: the
traceparent/tracestateheaders that propagate context across services.
Frequently Asked Questions
Is OpenTelemetry production-ready?
Yes. Traces are stable across all supported languages, metrics are stable in the major SDKs, and logs reached stability in the main languages. The Collector's core components are stable; check the status of individual contrib processors and exporters before depending on them.
Should I run the Collector as an agent, a gateway, or both?
Both for anything beyond a prototype. The agent (DaemonSet) receives telemetry close to the app and adds host metadata; the gateway aggregates, samples, filters, and exports. Small setups can start with a single gateway and add agents when nodes multiply.
What's the difference between head and tail sampling?
Head sampling decides at span start inside the SDK and can't see the outcome of the request. Tail sampling waits for the complete trace inside the Collector, so it can keep all errors and slow traces while sampling healthy traffic down. Head is cheap; tail is smarter and costs Collector memory.
Can I use OpenTelemetry with my existing Jaeger or Prometheus?
Yes. Jaeger ingests OTLP natively, and Prometheus can either scrape the Collector's prometheus exporter or receive prometheusremotewrite. You usually keep your backend and only change how data reaches it.
How do I migrate from a Jaeger client or a vendor agent?
Service by service. Swap the SDK, point exporters at OTLP, and keep the backend. For agents you can't replace, the Collector has zipkin, jaeger, and statsd receivers that accept legacy formats and feed them into OTel pipelines.
Which port does OTLP use, gRPC or HTTP?
gRPC is 4317, HTTP/protobuf is 4318. Most SDK defaults assume gRPC; firewalls and load balancers that struggle with gRPC can use the HTTP endpoint instead.
Related Resources
Complete Guide to Observability with the Grafana Stack
Set up the full Grafana observability stack: Prometheus, Loki, Tempo, Alloy and Grafana with a single docker-compose, correlation between signals, and SLO alerting.
RecipeDistributed Tracing with OpenTelemetry
How to implement distributed tracing in Python with OpenTelemetry SDK, including spans, context propagation, auto-instrumentation, and Jaeger export.
GuideSite Reliability Engineering
A practical guide to SRE: defining SLIs, SLOs, and SLAs, managing error budgets, toil reduction, on-call rotations, and building a culture of reliability.
GuideDistributed Tracing: OpenTelemetry, Jaeger, Zipkin
Master distributed tracing with OpenTelemetry, Jaeger, and Zipkin. Trace propagation across services, span context, sampling strategies, and production debugging.
GuideLog Aggregation — Centralize, Search
A practical guide to log aggregation: structured logging, shipping strategies, retention policies, and building searchable log pipelines with ELK, Loki, and cloud-native solutions.
RecipeImplement API Logging and Audit Trails
Set up request/response logging and audit trails that pass compliance reviews: structured output, correlation IDs, redaction, and append-only storage.